
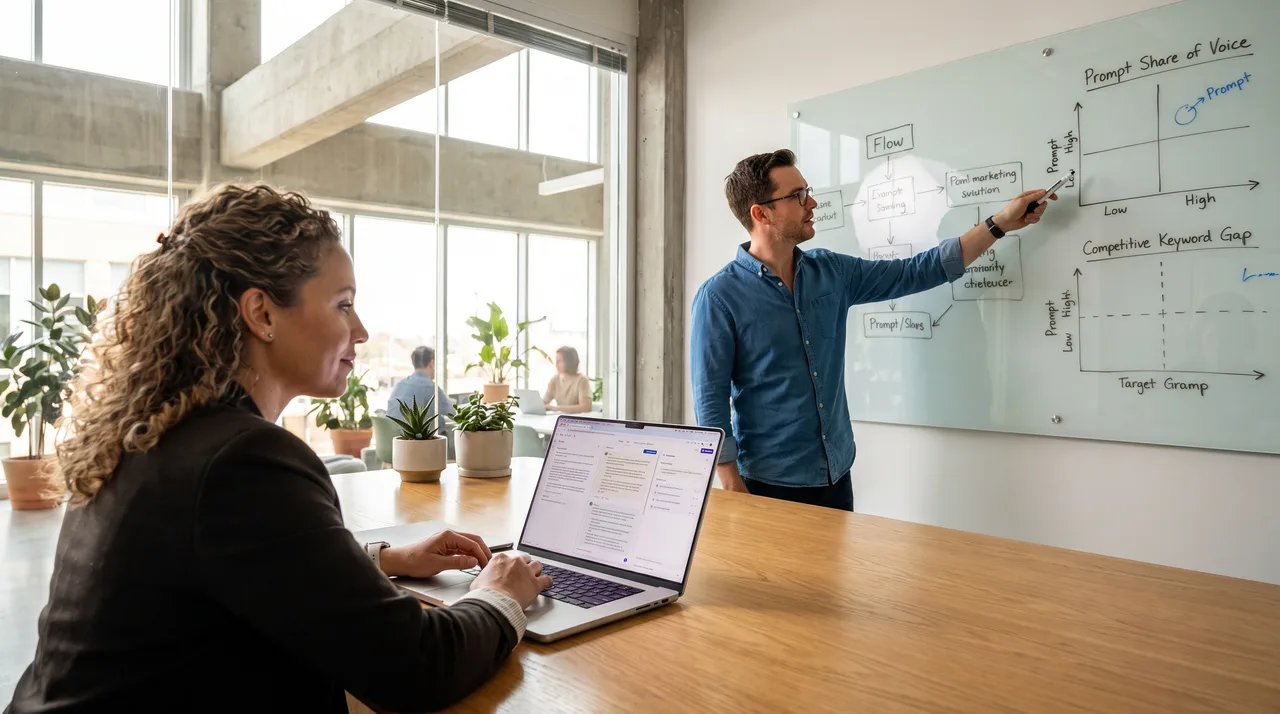
Ask ChatGPT, Gemini, or Perplexity for a recommendation, and the model names a few brands. If yours isn't among them, the deal is gone before you knew it existed. Here's the hard part: your competitors may already "own" the prompts that count most in your category, and you can't fix a gap you can't see.
This guide gives you a repeatable way to map which AI prompts keep surfacing rival brands instead of yours. Done right, that AI prompt research becomes the base for a lasting competitive strategy.
Why prompt ownership beats rankings
Old-school SEO taught us to think in keywords and blue links. Generative engines throw that out. Rather than ten results, users usually get one synthesized answer naming two or three brands. Being cited is binary in a way page-two rankings never were.
That scarcity is why competitor AI visibility now counts as a first-class metric. When a rival gets named in the answer to "best CRM for small agencies," they win attention, trust, and click intent in one sentence. You get nothing.
Think of a prompt as territory. Some are contested, some sit wide open, and some belong to a single brand the model has learned to trust. Your job is drawing the map.
Step 1: Build a prompt universe, not a keyword list
Begin by cataloging the questions real buyers put to AI tools across their journey. Group them into layers:
- Category prompts — "What are the best project management tools?"
- Use-case prompts — "Which tool is best for a remote design team?"
- Comparison prompts — "Asana vs Monday vs your brand"
- Problem prompts — "How do I stop losing track of client deliverables?"
- Trust prompts — "Is [brand] reliable for enterprise?"
Pull these from sales call transcripts, support tickets, Reddit threads, autocomplete data, and your existing keyword research. Aim for 100–300 prompts per category. This is your prompt universe, the generative-era version of a keyword corpus.
Prioritize by commercial value
Some prompts matter more than others. Score each on intent (informational vs purchase-ready), volume (how often the question comes up), and difficulty (how entrenched the incumbents are). Spend your first mapping pass on high-intent, high-volume prompts.
Step 2: Run prompts systematically across engines
Manual spot-checks don't scale, and they smuggle in bias. Run every prompt through the engines your audience uses — ChatGPT, Gemini, Perplexity, Copilot, and Claude — under controlled conditions.
A few discipline rules:
- Repeat each prompt multiple times. Outputs vary. A brand mentioned once in five runs is not the same as one named five times out of five.
- Strip personalization. Use clean sessions or logged-out states so history doesn't skew the results.
- Vary phrasing. Test three or four natural rewordings of each prompt to catch the real response distribution.
- Record structured data. Log the prompt, engine, run number, brands mentioned, citation order, and any linked sources.
The result is a dataset: for every prompt, which brands show up, how often, and where.
Step 3: Calculate share of voice per prompt
Now turn raw mentions into signal. For each prompt, work out share of voice — the percentage of runs where each brand gets named.
A simple version:
```
Brand SoV = (runs where brand is mentioned) / (total runs) x 100
```
Add position weighting if you want more nuance. Being named first matters more than being the fourth brand in a list. A weighted formula might give first mention 1.0, second 0.6, third 0.4, and so on.
Roll these numbers up to the category level for an overall share-of-voice picture, then drill down to find where the aggregate hides trouble.
Step 4: Find the prompts your competitors own
This is where the map pays off. Sort your dataset to surface three types of prompts:
Owned by rivals
Prompts where one competitor shows up in 80%+ of runs and you appear in under 20%. These are entrenched positions. The model has built a strong link between the query and that brand, usually from steady third-party citations, review presence, and topical authority.
Contested
Prompts where several brands, you included, swap appearances run to run. These are winnable with focused effort and offer your quickest path to better competitor AI visibility.
Open
Prompts where no brand dominates and answers stay generic. First movers can grab these cheaply before the category consolidates.
Plot them on a simple two-axis chart: commercial value on one axis, current ownership on the other. Your priority quadrant holds high-value prompts a rival owns or that stay contested.
Step 5: Diagnose why they own it
Ownership is an effect, not a cause. For each competitor-owned prompt, trace the sources the model cites. You'll usually spot one or more of these patterns:
- Citation density — the rival gets referenced across review sites, listicles, and comparison pages the model trusts.
- Entity clarity — their brand ties clearly to the topic through consistent structured data and messaging.
- Fresh, specific content — they publish answer-shaped content that matches the prompt's wording directly.
- Third-party endorsement — analysts, communities, and publications name them again and again.
Write down the mechanism behind each owned prompt. That diagnosis is your action plan.
Step 6: Turn the map into a roadmap
With gaps found and causes diagnosed, sequence the work:
- Defend contested high-value prompts first. You've got partial visibility already, so shore it up before rivals lock it in.
- Claim open prompts. Low competition means high return on modest effort.
- Chip away at owned prompts. These are long games. Go after the underlying citation gaps rather than expecting change overnight.
Re-run your AI prompt research on a set cadence — monthly for volatile categories, quarterly for stable ones. Track share-of-voice movement over time so you can prove impact and spot new competitors before they dig in.
Make prompt ownership a standing discipline
Generative engines are becoming the front door to purchase decisions. Treating prompt ownership as a one-off audit misses the point. The brands that win will keep mapping the prompt landscape, measuring share of voice, and acting on the gaps.
Build the prompt universe once, automate the measurement, and let the map show you exactly where competitors are winning conversations you should be in. That clarity separates guessing at your AI presence from managing it.